Agent tool selection Jev pattern
Given the current agent state, pick the next tool from a closed toolbox — including stop.
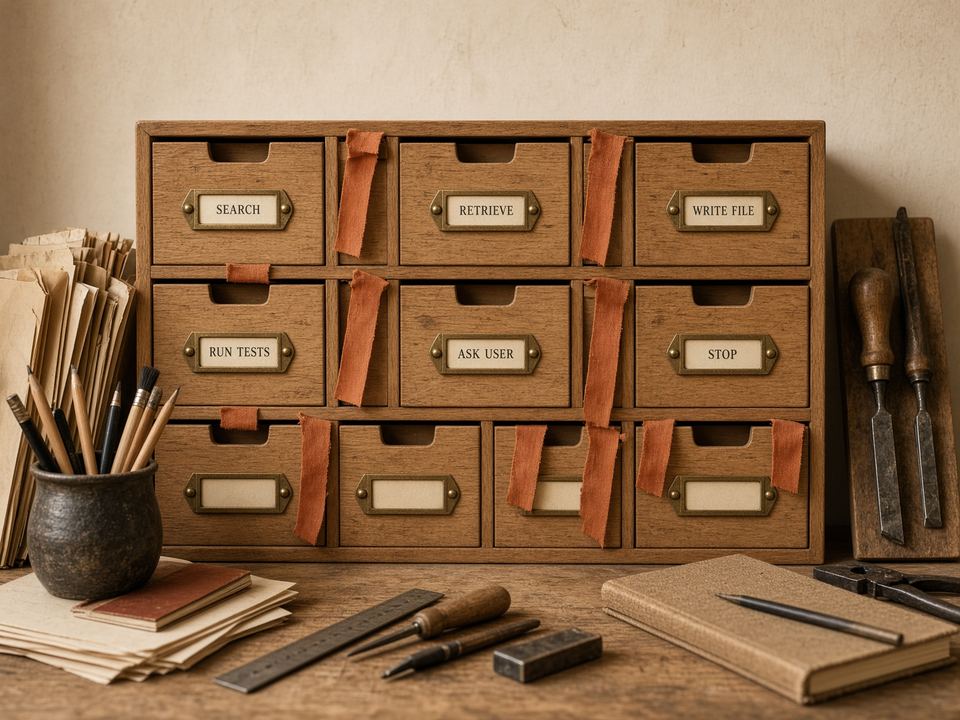
Tool-calling LLMs still sample tokens that happen to look like a function name. This pattern makes the toolbox a Choice. Put transcripts, the last observation, and the remaining budget in state. Put “stop” in the criteria so finishing is a first-class option, not an accident.
This agent tool selection schema is a paste-ready TypeSafe Jev request for jev-latest. Copy the JSON, keep thresholds in your code, and calibrate on your labels. Jev Patterns is independent and not affiliated with TypeSafe AI.
Use agent tool selection when
- An agent loop needs a next action from a known tool list.
- You want to forbid tools that are not in the list, by construction.
- You will execute the tool in your code, not ask the model to pretend it did.
Do not use agent tool selection when
- You need the model to write the tool arguments as prose.
- The toolbox is unbounded or invented per turn.
- The task is to chat with a user rather than act.
Confidence thresholds for agent tool selection
Keep these in your code. They are not part of the model call.
| When | Action |
|---|---|
| next_tool.confidence >= 0.70 | Execute next_tool.choice in the agent runtime |
| next_tool.choice == 'stop' | End the loop even if remaining_steps > 0 |
| next_tool.confidence < 0.70 | ask_user, or fall back to a reasoning model for one turn |
Pass examples
Failure is reproduced
The bug location is in context. retrieve or write_file, not search again.
{
  "goal": "Fix the failing test",
  "last_observation": "expected 401, received 200",
  "files_in_context": [
    "src/auth.ts"
  ]
}
Tests just passed
Stop. Remaining steps are a budget, not a requirement.
{
  "goal": "Fix the failing test",
  "last_observation": "1 passed, 0 failed",
  "remaining_steps": 2
}
Missing credential
ask_user. Do not invent a secret.
{
  "goal": "Deploy to staging",
  "last_observation": "DEPLOY_TOKEN is unset"
}
Ambiguous examples
Vague observation
Goal is not a task. Confidence should collapse toward ask_user or stop.
{
  "goal": "Make it better",
  "last_observation": "Done looking around."
}
Two equally good tools
search vs retrieve. If both are plausible, do not auto-execute.
{
  "goal": "Find where sessions are stored",
  "last_observation": "No files in context yet"
}
Looping search
The Choice does not know it is looping unless you put history in state.
{
  "goal": "Fix the failing test",
  "tools_already_used": [
    "search",
    "search",
    "search"
  ],
  "last_observation": "Same three files as before"
}
The problem agent tool selection is for
Function calling still samples tokens. Production traces are full of off-list names, invented paths, and the same search tool called four times with the same query. Vercel’s agent loop, LangChain’s max_iterations, and “force a done tool” posts all exist because the generator will not stop itself.
Agent tool selection is the decision of which tool to run next — not the arguments, not the patch, not the user-facing summary. A Choice over search | retrieve | write_file | run_tests | ask_user | stop cannot emit run_shell. You still execute in your runtime. You still need a writer if the tool needs a commit message. What you get from agent tool selection is the branch, with a distribution you can threshold.
Blog posts on tool choice tell you to write better descriptions. That helps. It does not close the answer space. Agent tool selection closes it.
Why this agent tool selection schema uses Jev
Put only tools you are willing to execute in criteria. If the agent must not run a shell, it is not an option. Agent tool selection will then never name a shell. Confidence tells you whether to proceed or ask the user.
stop is a first-class option, not a finish_reason you hope to see. ask_user is also first-class. Hidden “just keep going” is how loops burn tokens.
Do not ask Jev to fill arguments. Agent tool selection picks the tool. A coder model or your own templates fill paths, queries, and patches after the Choice.
What to put in state for agent tool selection
State should include the user goal, the last tool name, the last tool result truncated to what matters, file tree hints, and a step count. Agent tool selection without the last result will pick search again.
Pass a hard budget: steps_taken, max_steps. Put those numbers in state so the model can prefer stop when the loop is spent. Do not rely on instructions alone.
If tests already failed with a stack trace, put the trace in. write_file versus run_tests is obvious only with that evidence.
How to wire agent tool selection in code
If next_tool.confidence is below 0.70, call ask_user or stop even if the argmax is search. Show the distribution in the trace viewer.
Cap identical tool+args in your runtime regardless of the model. Agent tool selection is not a loop detector. It is a next-step enum. Keep a counter in code.
When the Choice is stop, do not generate a farewell chat line with Jev. Hand the transcript to a writer if you need a summary.
Eval plan: replay ten agent traces. At each step, hide the model’s actual tool call and ask whether agent tool selection would have picked the same verb. The interesting misses are search-loops and skipped stop. Fix criteria, then fix the runtime counter.
Failure modes
Argument generation
Jev will not write a regex or a file path. If you need arguments, keep a language model for that step after agent tool selection.
One giant tool named “code”
A single option teaches nothing. Split search, retrieve, write_file, run_tests. Criteria should match real functions.
Missing stop
Without stop on the list, the agent cannot end. max_iterations is then your only brake.
Copy, run, calibrate
The JSON in the rail is the agent tool selection request for jev-latest. Copy it into your stack, or open Agent tool selection in Jev Studio and draw the fixture bars. Thresholds stay in your repository. Calibrate on your labels before you auto-apply. Official model docs live at docs.typesafe.ai. Jev Patterns is independent and not affiliated with TypeSafe AI.
Related reading: Choice, Score, Noul, confidence thresholds, when not to use Jev.
Agent tool selection: FAQ
- What is agent tool selection in Jev Patterns?
- Agent tool selection is a Choice over the next tool an agent may run: search, retrieve, write_file, run_tests, ask_user, or stop. The list is closed by construction.
- How is agent tool selection different from function calling?
- Function calling still samples a tool name and JSON arguments. Agent tool selection returns a distribution over tools you declared. Arguments remain your job.
- Will agent tool selection stop loops by itself?
- No. Put stop on the list, pass steps_taken in state, and keep a same-tool counter in runtime. Agent tool selection is the enum, not the watchdog.
- Can I add shell or network tools to agent tool selection?
- Only if you are willing to execute them. Criteria is an allowlist. Off-list tools cannot be chosen.
- Does agent tool selection write the code?
- No. Jev does not generate code. After the Choice is write_file, a coder model or a patch template does the writing.
Last reviewed 21 September 2026. Independent of TypeSafe AI.
Next
Related Jev Patterns
Agents
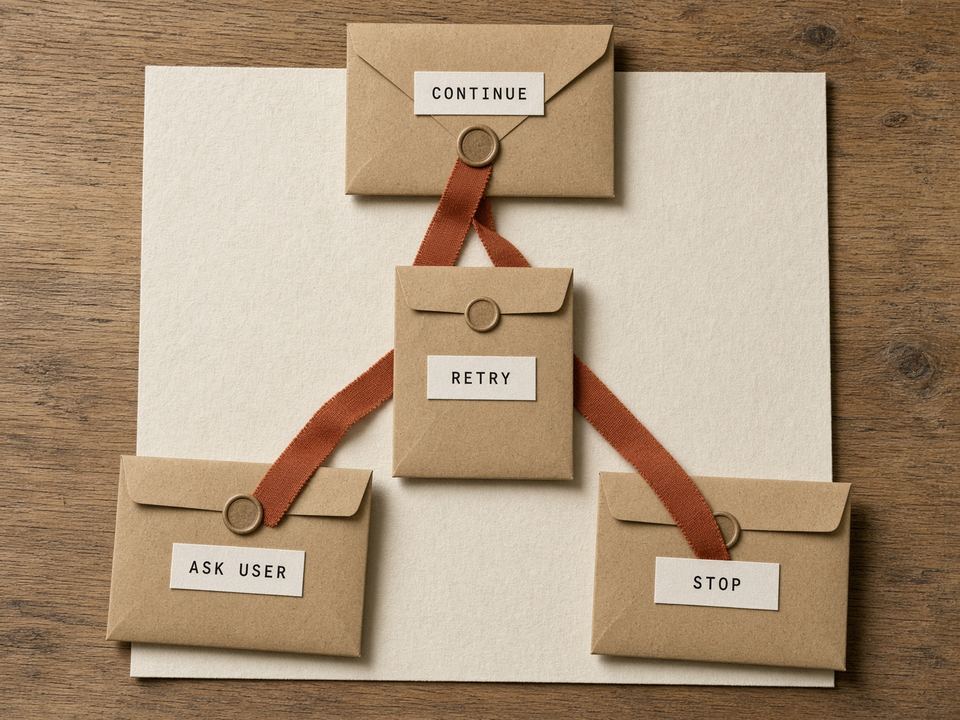
Agent continue or stop
After a tool result, decide whether to continue, retry, ask the user, or halt.
Support
Escalate to human
A single Noul: should a person take this over from the bot or the junior queue?
Guardrails
Eval judge
Given a claim and a passage, choose supports, contradicts, or says nothing.
Studio
Run Agent tool selection in Studio
Fixture bars first. Optional live call stays in this browser.