Eval judge Jev pattern
Given a claim and a passage, choose supports, contradicts, or says nothing.
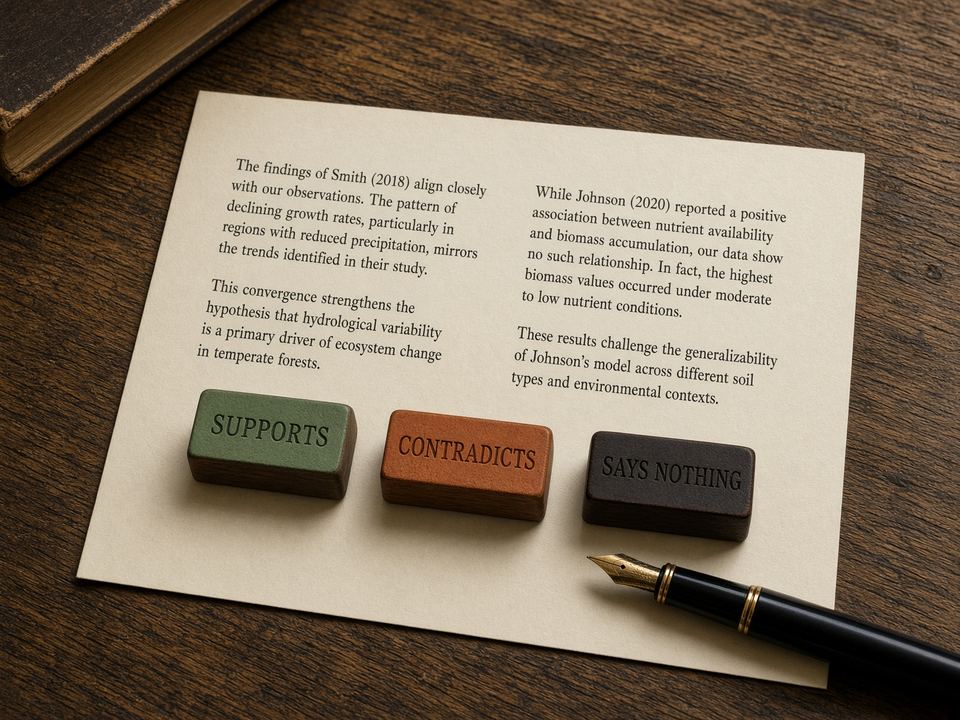
LLM-as-judge usually means “write a paragraph and a score from 1–5.” That is slow, and the score is not a probability. This Choice forces a closed verdict your eval harness can count. Use it to grade RAG answers, agent traces, or extracted facts against source text.
This eval judge schema is a paste-ready TypeSafe Jev request for jev-latest. Copy the JSON, keep thresholds in your code, and calibrate on your labels. Jev Patterns is independent and not affiliated with TypeSafe AI.
Use eval judge when
- You are building an eval set and need a consistent verdict per pair.
- You want to know if a claim is supported, not how well it is written.
- Says-nothing is a real outcome and should not be folded into contradicts.
Do not use eval judge when
- You need a written critique of the answer.
- The passage is not in state.
- You are scoring style, tone, or helpfulness — that is a different rubric (use Score).
Confidence thresholds for eval judge
Keep these in your code. They are not part of the model call.
| When | Action |
|---|---|
| verdict.confidence >= 0.75 | Record verdict.choice as the eval label |
| verdict.confidence < 0.75 | Send to a human labeler; do not poison the eval set |
Pass examples
30 vs 14
contradicts. The window is material.
{
  "claim": "Pro refunds are available for 30 days after purchase.",
  "passage": "Pro subscriptions may be refunded within 14 days of first charge."
}
Faithful
supports.
{
  "claim": "Pro refunds are available within 14 days of first charge.",
  "passage": "Pro subscriptions may be refunded within 14 days of first charge."
}
Different topic
says_nothing. Do not treat silence as a contradiction.
{
  "claim": "Pro includes SSO.",
  "passage": "Pro subscriptions may be refunded within 14 days of first charge."
}
Ambiguous examples
Under-specified claim
Supports a weaker claim, or says_nothing about which plan. Tighten the claim.
{
  "claim": "Refunds are available.",
  "passage": "Pro subscriptions may be refunded within 14 days of first charge."
}
Implied number
Two weeks ≈ 14 days. Decide whether paraphrase counts as supports.
{
  "claim": "You have two weeks to request a Pro refund.",
  "passage": "Pro subscriptions may be refunded within 14 days of first charge."
}
Conflicting sentences
Which Pro? Low confidence is the right outcome.
{
  "claim": "Pro refunds are 14 days.",
  "passage": "Pro: 14 days. Legacy Pro: 30 days."
}
The problem eval judge is for
LLM-as-judge evals ask a chat model to score 1–5 and explain. Teams then parse the explanation, argue about the rubric, and discover the judge prefers long answers. Academic NLI labels — entailment, contradiction, neutral — are the cleaner task. Eval judge is that task as a Choice: supports, contradicts, says_nothing.
Use it for RAG claim checks, for gold-labeling retrieval, and for regression tests when a writer changes. Do not use eval judge to pick the “nicer” email. Style is generation taste. This is a relation between a claim and a passage.
The Choice cannot return “mostly supports.” If you need a gradient, add a Score. Start with the three-way label; it matches how humans actually tag.
Why this eval judge schema uses Jev
says_nothing is the underrated label. Most retrieved chunks neither support nor contradict a specific claim. Forcing a winner poisons the eval. Eval judge keeps the third door.
Confidence is peakedness of that three-way distribution. A 0.40 / 0.32 / 0.28 split is not a label. Skip it or send it to a human tagger.
Jev will not write a rationale paragraph. If your eval UI needs a highlight, store the passage offsets yourself or use a different tool. The judge is the label.
What to put in state for eval judge
State is claim plus passage (and source id). Keep the claim atomic. “The product is down in eu-west-1 since 14:00 UTC” is a claim. A whole email is not.
Do not include the writer’s answer unless that is the claim you are judging. Eval judge on “the draft” mixed with “the docs” is a different pattern — the LLM output guardrail.
For pairwise model evals (“which answer is better”), this is the wrong primitive. That is preference. Use a human or a preference model. Eval judge is NLI-shaped.
How to wire eval judge in code
Map supports → pass claim, contradicts → fail claim, says_nothing → skip. Aggregate across claims for a groundedness score of a draft. That composition lives in your evaluator, not in Jev.
If confidence < 0.70, exclude the item from the automated score and sample it for humans. Eval judge noise at the middle will swing leaderboards.
Pin jev-latest or a versioned id when the eval is a gate on deploy. Aliases move. TypeSafe documents this; believe them.
Eval plan: humans label 100 claim–passage pairs with the same three keys. Measure eval judge agreement and the confidence of disagreements. If says_nothing is never used, raters or criteria are forcing a winner — fix that before you trust a leaderboard.
Failure modes
Asking for a 1–5 and a paragraph
That is a chat judge. Eval judge is a closed Choice. Keep the rationale out.
Multi-claim blobs
Split claims. One Choice per atomic statement or you will not know what contradicted.
Using this as a writer
It will not fix the claim. It will label the relation.
Copy, run, calibrate
The JSON in the rail is the eval judge request for jev-latest. Copy it into your stack, or open Eval judge in Jev Studio and draw the fixture bars. Thresholds stay in your repository. Calibrate on your labels before you auto-apply. Official model docs live at docs.typesafe.ai. Jev Patterns is independent and not affiliated with TypeSafe AI.
Related reading: Choice, Score, Noul, confidence thresholds, when not to use Jev.
Eval judge: FAQ
- What is the eval judge Jev pattern?
- Eval judge is a Choice of supports, contradicts, or says_nothing for a claim against a passage. It is an NLI-shaped label with a confidence you can threshold.
- How is eval judge different from LLM-as-judge rubrics?
- Those usually generate a score and a paragraph. Eval judge constrains the label set and does not generate text.
- Why include says_nothing in eval judge?
- Most passages are irrelevant to a specific claim. Forcing support or contradict invents signal.
- Can eval judge pick the better model answer?
- Not this schema. Pairwise preference is a different job. Use eval judge for claim–passage relations.
- Should eval judge run in production or only in CI?
- Both. In production it is a cousin of the LLM output guardrail. In CI it is a frozen labeler — pin the model version.
Last reviewed 21 September 2026. Independent of TypeSafe AI.
Next
Related Jev Patterns
Guardrails
LLM output guardrail
Decide whether a generated answer is grounded in the sources you actually retrieved.
Guardrails
RAG chunk relevance
Score each retrieved chunk on a 0–3 rubric before it is stuffed into the writer prompt.
Ops
Refund eligibility
Ask two Nouls: did they request a refund, and does the policy you passed in support one?
Studio
Run Eval judge in Studio
Fixture bars first. Optional live call stays in this browser.