LLM output guardrail Jev pattern
Decide whether a generated answer is grounded in the sources you actually retrieved.
Let the LLM write. Let Jev judge. This pattern takes the draft, the retrieved sources, and the user question, then returns a groundedness Noul plus a pass / revise / block Choice. Blocking is a product decision you keep in code.
This LLM output guardrail schema is a paste-ready TypeSafe Jev request for jev-latest. Copy the JSON, keep thresholds in your code, and calibrate on your labels. Jev Patterns is independent and not affiliated with TypeSafe AI.
Use LLM output guardrail when
- An LLM is answering from a known source set (docs, tickets, RAG).
- You would rather revise or refuse than ship a fluent hallucination.
- Groundedness and policy are separate questions on the same draft.
Do not use LLM output guardrail when
- There are no sources — groundedness is undefined.
- You want Jev to rewrite the answer. It will not generate text.
- The draft is code that needs a compiler, not a judge.
Confidence thresholds for LLM output guardrail
Keep these in your code. They are not part of the model call.
| When | Action |
|---|---|
| grounded_in_sources.noul >= 0.80 && verdict.choice == 'pass' | Show the draft |
| verdict.choice == 'revise' || grounded_in_sources.noul < 0.80 | Regenerate with a stricter prompt, max twice |
| verdict.choice == 'block' | Return a canned “I can’t find that in the docs” |
Pass examples
Invented 30-day window
Not grounded. revise or block. The writer was fluent and wrong.
{
  "question": "Refund window on Pro?",
  "sources": [
    {
      "text": "Refunded within 14 days of first charge."
    }
  ],
  "draft": "Full refund in the first 30 days, no questions asked."
}
Faithful paraphrase
pass. Paraphrase is allowed; new numbers are not.
{
  "sources": [
    {
      "text": "Refunded within 14 days of first charge."
    }
  ],
  "draft": "Pro refunds are available within 14 days of the first charge."
}
Unknown, honestly
pass. Refusing is grounded.
{
  "question": "Do you refund crypto payments?",
  "sources": [
    {
      "text": "Refunded within 14 days of first charge."
    }
  ],
  "draft": "The retrieved policy does not mention crypto payments."
}
Ambiguous examples
Soft extra advice
The extra advice is not in sources. Your product may still want revise.
{
  "sources": [
    {
      "text": "Refunded within 14 days of first charge."
    }
  ],
  "draft": "Refunds are available within 14 days. I'd do it sooner to be safe."
}
Stale source vs draft
Grounded in what you retrieved. Freshness is a retrieval problem.
{
  "sources": [
    {
      "text": "Refunded within 14 days (v3, 2024)."
    }
  ],
  "draft": "Refunds are available within 14 days."
}
Empty retrieval
No sources. Do not call this pattern; short-circuit to block.
{
  "sources": [],
  "draft": "It's 14 days."
}
The problem LLM output guardrail is for
RAG blogs now agree: generation is not a grounding check. DZone lists relevance scoring, forced citations, NLI, staleness, and confidence. Bedrock Guardrails expose grounding and relevance floats. Those are the right jobs. They are usually a second model or an embedding cosine, not the writer grading its own homework.
An LLM output guardrail should not be “please admit if you made this up.” Writers are trained to sound sure. The Jev pattern sends the draft, the sources, and two questions: a Noul grounded_in_sources, and a Choice verdict pass | revise | block. The writer never sees the gate.
This LLM output guardrail is for software that must refuse. Support macros, RAG answers, policy chat. Not for creative writing.
Why this LLM output guardrail schema uses Jev
grounded_in_sources is a Noul: probability the draft is supported by the supplied sources. verdict is a Choice so your code has a switch. Mixing them in one call is the point of System One — parallel, isolated questions on the same state.
block is for “this should not ship.” revise is for “send it back to the writer with the missing claim.” pass is for “serve.” Do not invent a fourth option named “mostly.”
Jev cannot invent a citation URL. If sources are missing from state, the Noul should collapse toward unsure. That is a feature.
What to put in state for LLM output guardrail
State needs the user question, the draft, and the source excerpts actually retrieved — not a pointer to a vector store. An LLM output guardrail that cannot see the chunks cannot judge them.
Include citation markers if the writer used them. If the draft cites [3] and chunk 3 is absent, pass that fact.
Do not send the writer’s chain-of-thought. Send the text a user would see.
How to wire LLM output guardrail in code
If grounded_in_sources.noul is below 0.35, prefer block even if verdict.choice is pass. The Noul is the safety number; the Choice is the action. Disagree in code, not in the prompt.
revise should re-enter the writer with the same sources and a constrained instruction from your template, not from Jev. Jev will not write the revision.
Log both answers. An LLM output guardrail eval is “would a human have blocked this,” not “did the Choice look confident.”
Eval plan: take 50 drafts a human already marked hallucinated or clean. Run the LLM output guardrail with the same sources. Tune grounded_in_sources first; let verdict follow. If pass wins on empty sources, your state packing is wrong.
Failure modes
Self-grading
Never ask the writer to fill grounded_in_sources. The LLM output guardrail is a second call on jev-latest.
Empty sources
If retrieval returned nothing, skip generation or force block. Do not run the guardrail on an empty array and call it grounded.
Creative tasks
Poems and brainstorms are not grounded. Do not use this LLM output guardrail there.
Copy, run, calibrate
The JSON in the rail is the LLM output guardrail request for jev-latest. Copy it into your stack, or open LLM output guardrail in Jev Studio and draw the fixture bars. Thresholds stay in your repository. Calibrate on your labels before you auto-apply. Official model docs live at docs.typesafe.ai. Jev Patterns is independent and not affiliated with TypeSafe AI.
Related reading: Choice, Score, Noul, confidence thresholds, when not to use Jev.
LLM output guardrail: FAQ
- What is the LLM output guardrail pattern?
- The LLM output guardrail is a Jev schema that scores whether a draft is grounded_in_sources (Noul) and picks pass, revise, or block (Choice) against the retrieved excerpts.
- Does the LLM output guardrail replace Bedrock Guardrails?
- No. It is an independent schema for TypeSafe Jev. Bedrock, llm-guard, and Galileo solve overlapping jobs with different models. This site is not affiliated with them or with TypeSafe AI.
- Can the LLM output guardrail write a safer answer?
- No. Jev does not generate text. revise means you call the writer again. block means you refuse.
- What if grounded_in_sources is 0.5?
- 0.5 means unsure, not half-true. Treat the middle as revise or human review, not as pass.
- Should the writer see the LLM output guardrail questions?
- No. Keep the gate off the writer’s context so it cannot talk its way through.
Last reviewed 21 September 2026. Independent of TypeSafe AI.
Next
Related Jev Patterns
Guardrails
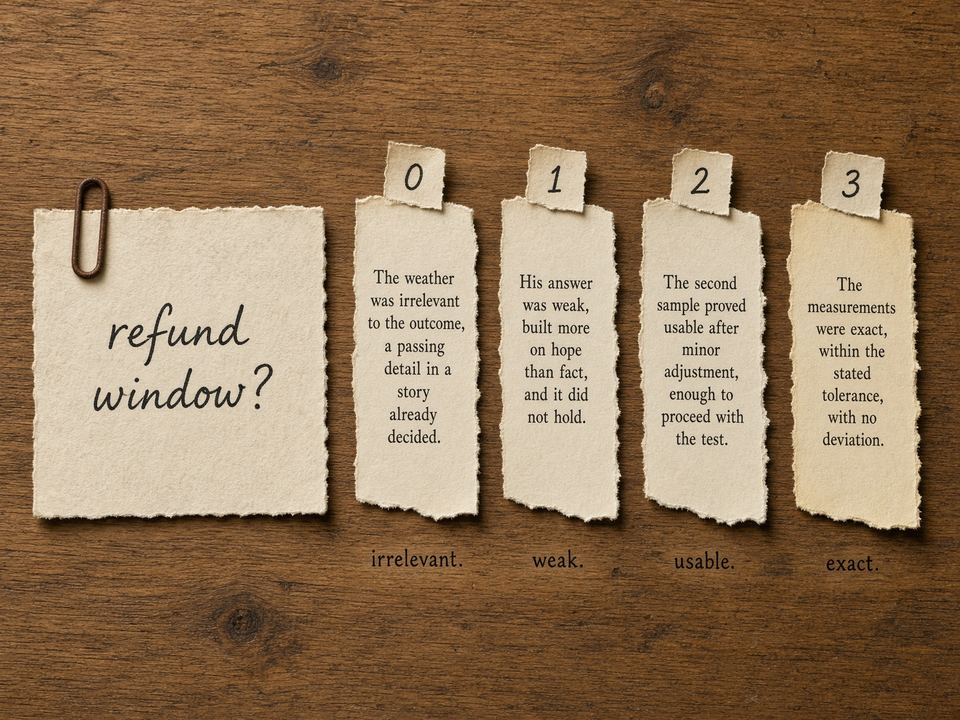
RAG chunk relevance
Score each retrieved chunk on a 0–3 rubric before it is stuffed into the writer prompt.
Guardrails
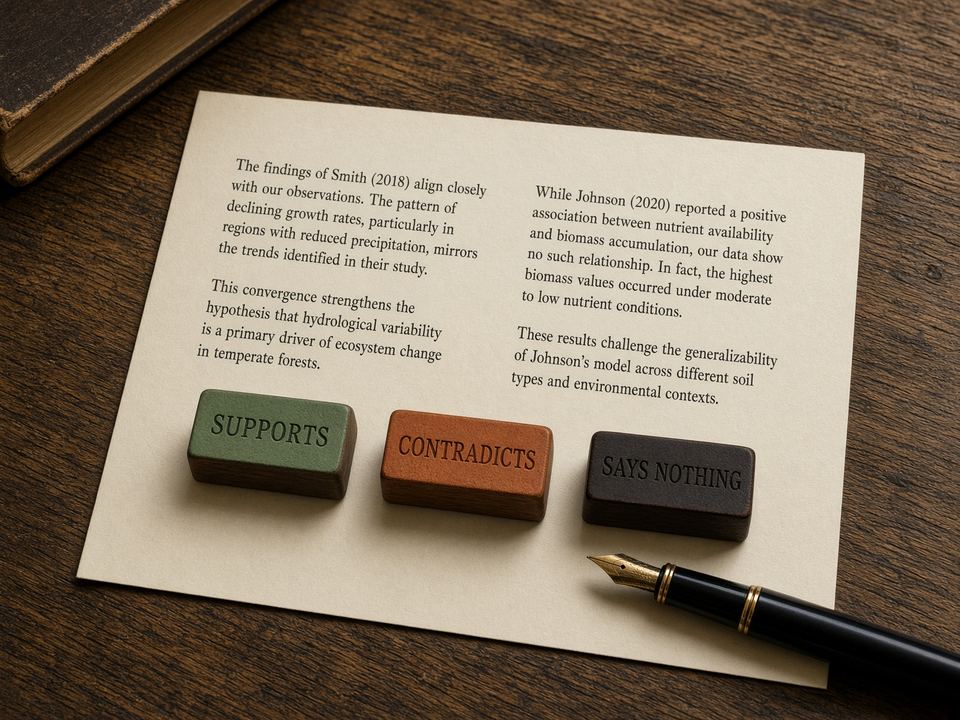
Eval judge
Given a claim and a passage, choose supports, contradicts, or says nothing.
Moderation
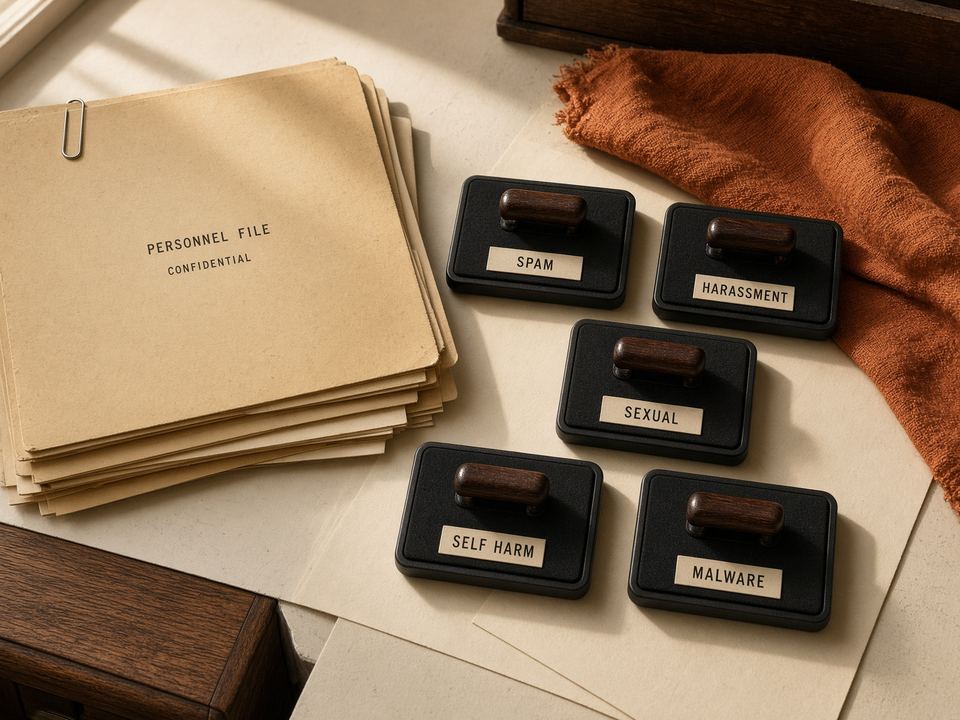
Content moderation screen
Run independent Nouls for spam, harassment, sexual content, self-harm, and malware.
Studio
Run LLM output guardrail in Studio
Fixture bars first. Optional live call stays in this browser.