Compare
Jev vs JSON
Jev is not JSON mode. You send JSON. You get Choice, Score, and Noul — not a blob to parse. Constrained braces are not a closed answer space.
Searching “jev json”? Jev vs JSON mode starts there. JSON mode (and schema-guided decoding) is a decoder constraint: the model is steered toward tokens that keep the document valid JSON, sometimes valid against a JSON Schema. OpenAI said this plainly when they shipped structured outputs in 2024: JSON mode does not guarantee schema adherence; structured outputs do. Production 2026 guides still say: validate business logic even when the JSON is perfectly shaped.
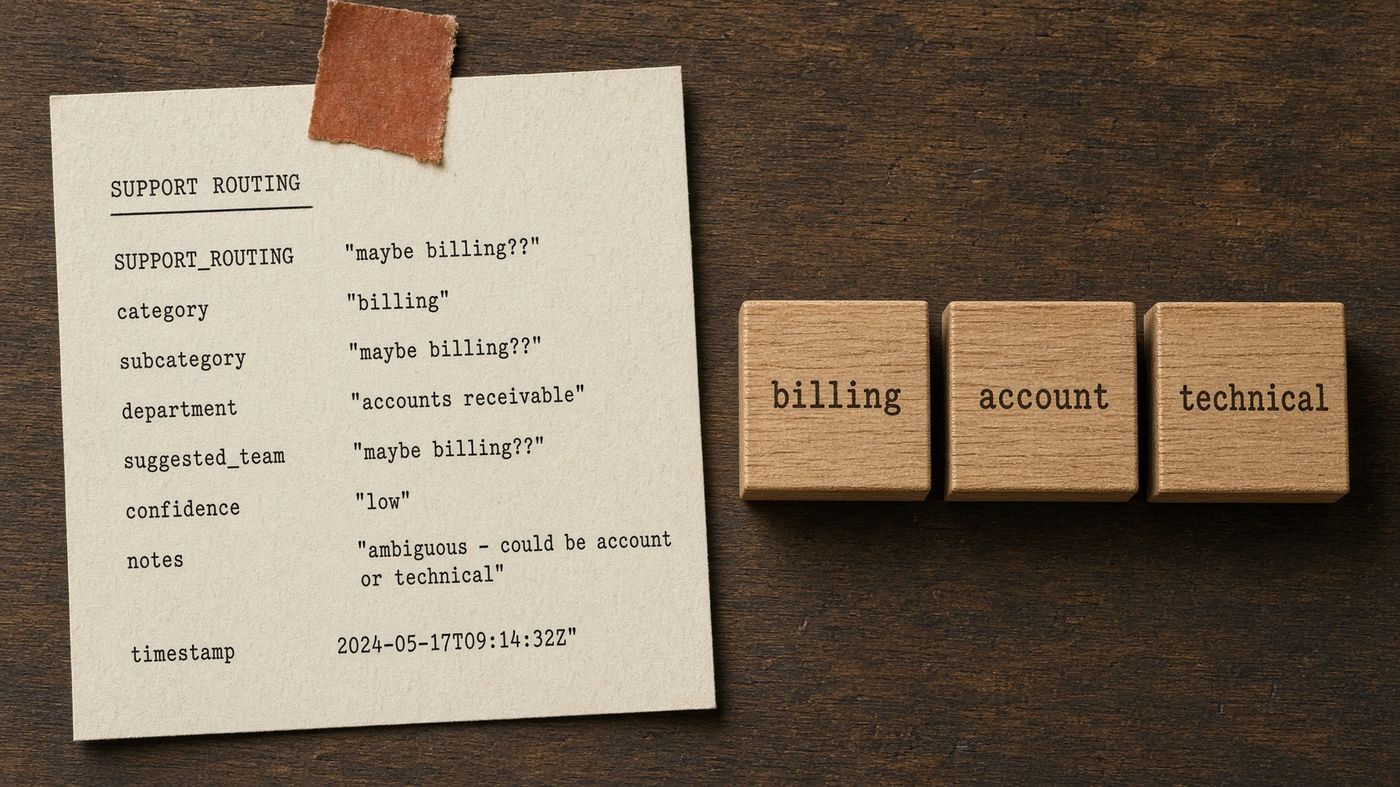
You get fewer truncated objects. You do not get a probability over account | billing | technical. The remaining failures are semantic. The object is well-formed and wrong: "department": "finance" when your enum said billing. Extra keys in non-strict modes. A string where you wanted a boolean. A "confidence": "high" invented as prose. You validate, retry, and quietly distrust the number. Jev vs JSON is whether you still want a document at all.
Does Jev return JSON?
You POST JSON. You do not parse a generated JSON blob. The response keys match the question keys: a Choice distribution, a Score on a rubric, or a Noul probability. There is no "department": "maybe billing" string to regex. If you need open strings — a company name, a tracking number — that is still a writer job with JSON mode. Jev vs JSON is specifically the closed fields you were already treating as enums and then repairing.
Feature contrast
| Property | JSON mode | Structured outputs | Jev |
|---|---|---|---|
| Valid JSON | Yes | Yes | You send JSON; answers are typed fields |
| Schema / enum adherence | No | Yes (supported schemas) | Criteria are the enum |
| Calibrated distribution | No | No | Yes |
| Generates field prose | Yes | Yes | No |
| Best for | Legacy clients | Extraction, writer payloads | Routing, scoring, gates |
By construction
Jev’s Choice criteria are the enum. The response is a distribution that sums to one over those keys, plus a confidence derived from peakedness. A Score cannot return 7 on a 0–3 rubric. A Noul cannot return “maybe.” There is no document to repair. That is the entire product difference this library is about. Not “Jev writes better JSON.” Jev does not write JSON for you to parse. You send JSON. You get answers keyed the same way.
Structured outputs deserve credit: they closed a lot of the syntax tax. Gemini docs still tell you to validate. Anthropic often goes through tools. None of those stacks give you peakedness on a System One primitive. Keep JSON mode for the writer. Keep Jev for the judge. Jev vs JSON mode is a split, not a migration threat.
Migration notes for Jev vs JSON
If you already have Zod-validated JSON from a writer, you do not have to throw it away. Keep it for extraction (invoice fields, names, dates) where the values are open strings. Replace the enum fields — department, next_tool, verdict — with Jev Choices. Replace invented confidence strings with peakedness. That hybrid is the honest Jev vs JSON migration: not a big-bang rewrite.
Watch token cost. A writer JSON blob is metered on output. Jev’s output is unmetered at TypeSafe’s published list, with a tiny typed payload. For a classifier you call on every ticket, that difference is the budget. For a once-a-day extraction job, JSON mode on a cheap writer may still be fine. Pick on frequency and on whether the value is an enum.
Related: function calling, what is Noul in Jev, support ticket routing. Independent site, not affiliated with TypeSafe AI or OpenAI. Last reviewed 22 September 2026.
A ticket classifier: Jev vs JSON in one pipeline
Old path: prompt a writer to emit {"department": "...", "urgent": true, "confidence": "high"}. Validate with Zod. Retry on enum miss. Log the retries. Argue about “high.” New path: Jev Choice over your queues plus a Noul for urgency. Branch on peakedness. The writer, if any, runs after, for the customer sentence. That is Jev vs JSON as a diff you can ship in an afternoon.
Keep JSON mode where the value is an open string: the customer’s company name, a quoted error code, a tracking number. Jev will not invent a string primitive. Structured extraction is still a generator job with a schema. Jev vs JSON is specifically the closed fields you were already treating as enums and then repairing.
Open Jev Studio on routing if you want to see the distribution instead of imagining it. Then read confidence thresholds so you do not auto-apply 0.51.
Jev vs JSON FAQ
- Does Jev output JSON?
- You send JSON (state + questions). You get typed answers under the same keys — a Choice, a Score, or a Noul — not a free-form JSON document to repair. That is Jev vs JSON mode.
- What is Jev vs JSON mode?
- JSON mode (and structured outputs) constrain braces on a generator. Jev constrains the answer space: closed Choice / Score / Noul with probabilities. Not the same product.
- Is Jev the same as JSON mode?
- No. JSON mode still samples field values as language. Jev vs JSON is a different model class. Keep JSON mode for extraction. Keep Jev for routing, scoring, and gates.
- Does JSON mode give me a probability over my enum?
- No. You might prompt for a confidence field. That field is still sampled language. Jev vs JSON mode is the difference between a number you invented and a distribution over keys you declared.
- Should I keep JSON mode for the writer?
- Yes. Jev vs JSON is not “never generate JSON.” Keep JSON mode or structured outputs for extraction and writer payloads. Keep Jev for the judge.
- Can structured outputs emit an invalid enum?
- If the schema lists the enum, strict decoding should not emit off-list keys. It can still pick the wrong on-list key with no calibrated peakedness. That is the remaining Jev vs JSON gap.
- Is this Jev vs JSON page affiliated with OpenAI or TypeSafe?
- No. Jev Patterns is independent. Not affiliated with TypeSafe AI or OpenAI.
Next
Keep comparing
Last reviewed 16 October 2026. Independent of TypeSafe AI.